
A Kubernetes upgrade starts at two in the morning and drains nodes one at a time. One of those nodes hosts the Postgres primary.
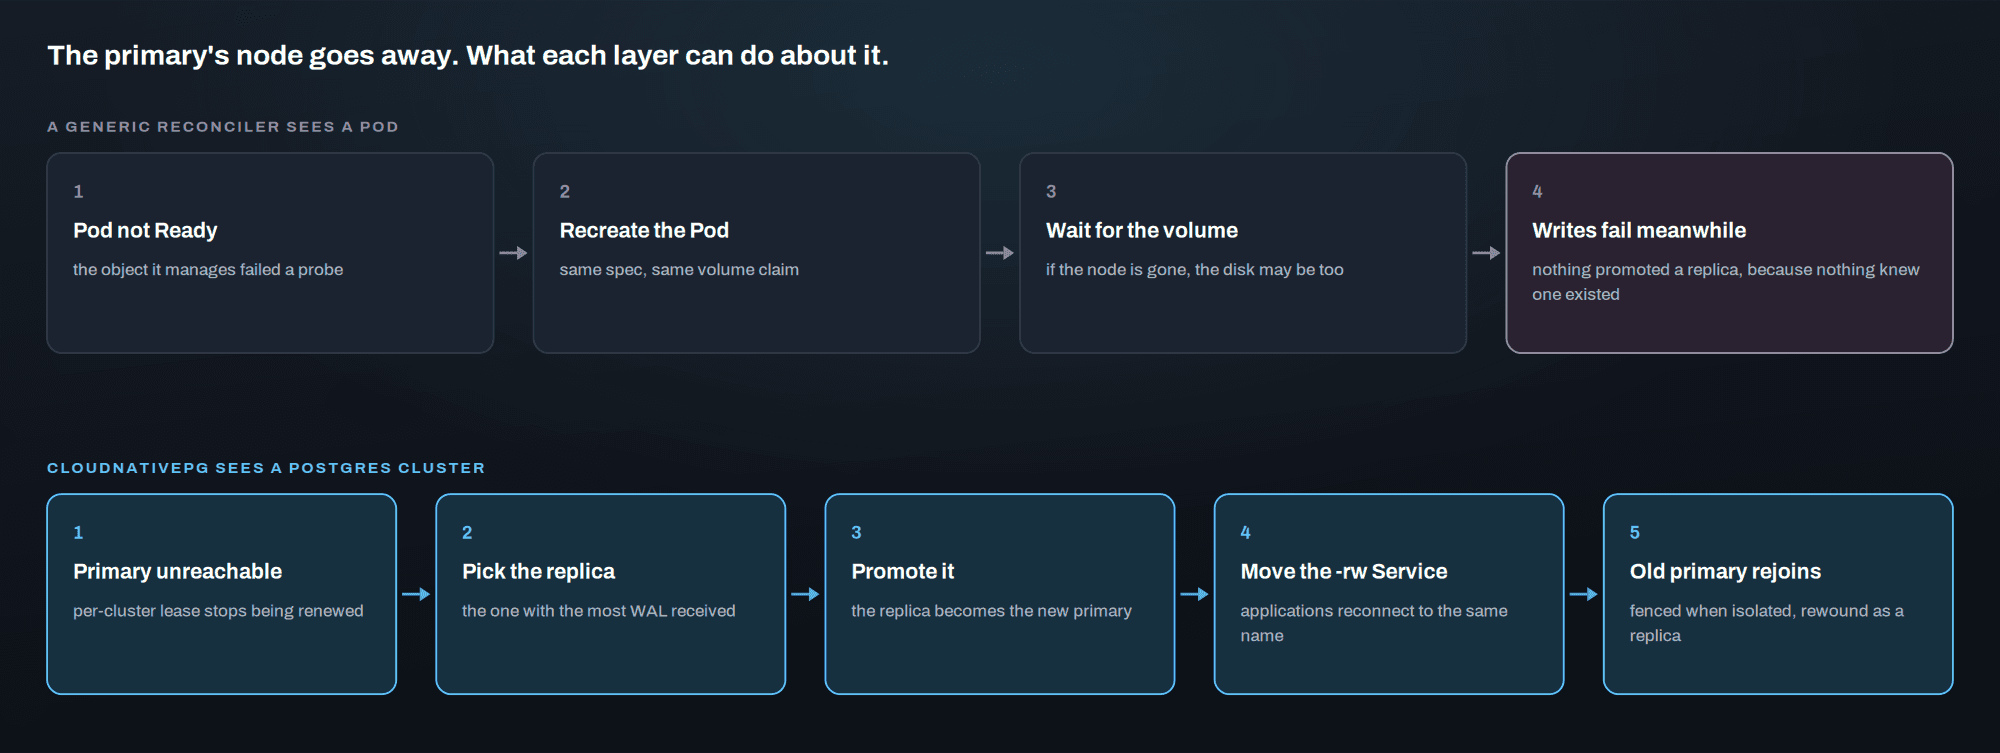
If that database is a StatefulSet from a Helm chart, the pod is evicted, rescheduled, and waits for its volume to follow it. Every write fails in the meantime, and if the storage is local to the node, the wait lasts until the node comes back. Nothing promoted a replica, because nothing in that setup knew a replica was a candidate for promotion.
If the database is a CloudNativePG cluster, the operator notices the drain, switches the primary over to a replica before the eviction happens, and lets the drain continue once the old primary has been demoted. Applications see a reconnect. The upgrade carries on and nobody is paged.
Both setups passed the same test on the day they were created: a database exists, the application connects, the migrations ran. The difference only shows up on the days after, and that is the whole argument of this article. We run Postgres on Kubernetes with CloudNativePG rather than a generic provisioning layer, because provisioning was never the hard part. Operating the database is.
The question is not "can it create a database"
CREATE DATABASE is the easy 10%
When teams compare options for Postgres on Kubernetes, the comparison usually starts in the wrong place. Can it create an instance? Can it create a database and a role? Can the application get a connection string from a Secret?
Everything can. A Helm chart can, a Terraform provider can, a composition in a universal control plane can, and so can a shell script in a pipeline. If the criterion is getting a database to exist, the options are indistinguishable, and the cheapest one wins by default.
The hard 90% comes after
A database is not a stateless deployment that you can recreate from its spec. It holds the only copy of something, it has a role (primary or replica) that changes at runtime, and it accumulates history that you may need to rewind to a specific second. Every one of those properties generates work after the first day.
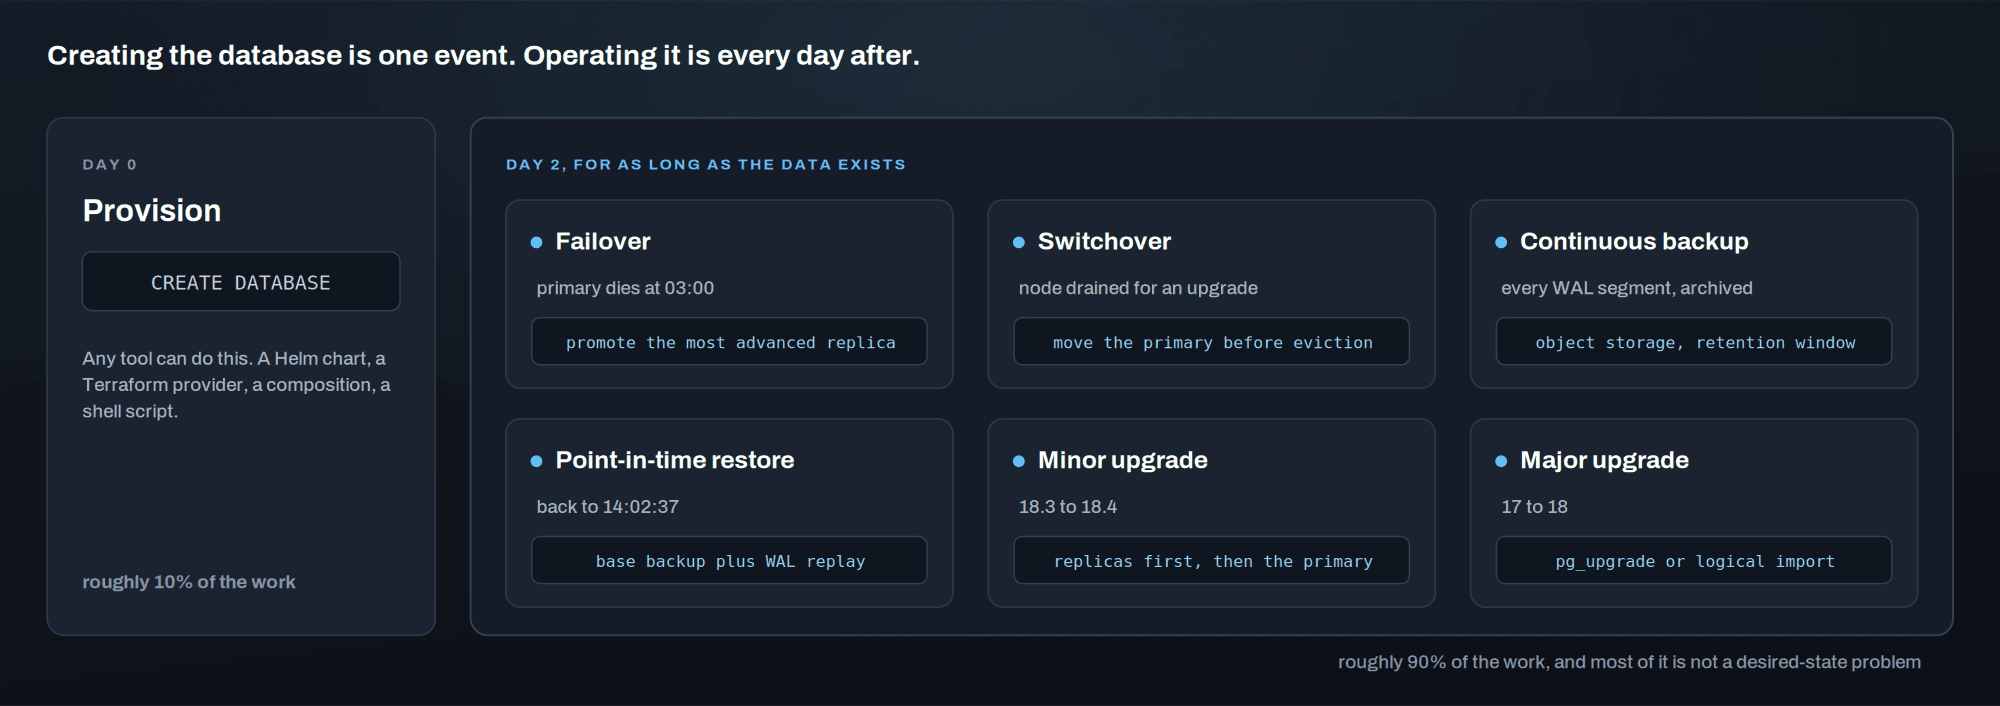
Provisioning happens once. Everything in the right-hand panel happens repeatedly, often at night, and each item needs logic that understands Postgres.
So the useful question is not whether a tool can create a database. It is what the tool does when the primary dies, when you need to restore to 14:02:37, when the minor version has a CVE fix, and when the next major version ships. That reframes the comparison from provisioning to operating, and on that axis the options stop being equivalent.
What a Postgres-specific operator actually does
CloudNativePG is a Kubernetes operator built around the Postgres lifecycle. It started at EDB, was released under Apache 2.0, and is now a CNCF Sandbox project. The centre of its API is one custom resource, Cluster, which describes a primary, its replicas, their storage, and how they are backed up.
Everything that follows is driven from that manifest, and it lives in Git next to the application that uses it, applied by Argo CD like any other resource.
Failover without a sidecar
Most Postgres operators delegate high availability to Patroni, a separate process that runs next to Postgres and coordinates leadership through a distributed configuration store. CloudNativePG does not. Each pod runs the operator's own instance manager as its entrypoint, and high availability is coordinated directly through the Kubernetes API, with no external tools.
When the primary becomes unreachable, the operator promotes the replica with the most up-to-date data, coordinated by a per-cluster lease that prevents premature promotion. Applications connect through three operator-managed Services: orders-db-rw always points at the current primary, orders-db-ro at the replicas, and orders-db-r at any instance. Failover moves the -rw Service, so the application's connection string never changes.
Two details matter more than they look. Since version 1.27, an isolated primary shuts itself down within the liveness probe timeout, 30 seconds by default, which is the fencing step that keeps a network partition from producing two primaries accepting writes. And version 1.28 promoted quorum-based failover to stable, which, combined with synchronous replication, lets you trade some write latency for a guarantee that a promoted replica has every committed transaction.
There is one more design decision underneath this. CloudNativePG does not use StatefulSets. It manages Pods and PersistentVolumeClaims directly, because a StatefulSet assumes interchangeable replicas with stable ordinals, and a Postgres cluster is not that. One instance is special, which instance that is changes over time, and an operator that knows this can reattach, resize or rebuild a specific instance's volume without going through an abstraction designed for something else.
Continuous backup and point-in-time recovery
Backups are continuous rather than nightly. The primary archives every WAL segment to object storage as it is produced, and scheduled base backups give the recovery process a starting point. Since version 1.26 this runs through the Barman Cloud plugin rather than code built into the operator, and the backup configuration moves into its own resource.
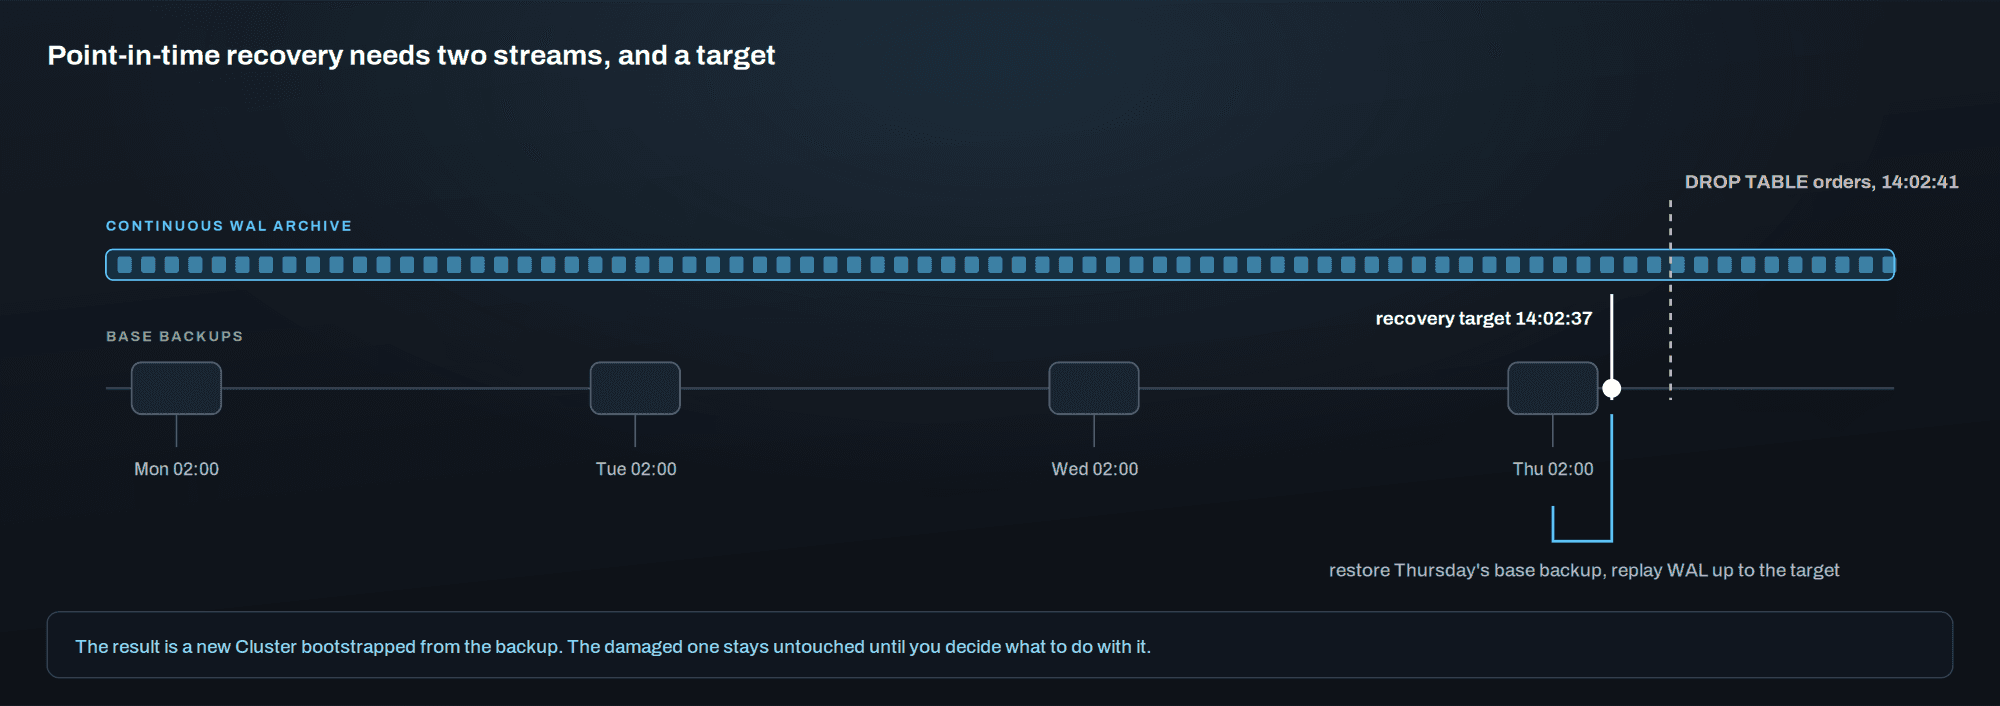
The payoff is point-in-time recovery. Someone runs a destructive statement at 14:02:41. You do not restore last night's backup and lose the day. You ask for the cluster as it was four seconds earlier.
Recovery restores the nearest base backup before the target, then replays archived WAL up to the exact moment you asked for.
Recovery always produces a new Cluster. The damaged one is left exactly as it was, which means you can compare the two, extract what you need, and decide how to cut over, instead of overwriting the only evidence of what went wrong.
Minor and major upgrades
A minor upgrade is a change to the image tag. The operator updates the replicas first, one at a time, then handles the primary according to primaryUpdateMethod: switchover promotes an already-updated replica so the outage is a reconnect, while restart restarts the primary in place.
Major upgrades used to be the part everyone scripted by hand. Since 1.26, CloudNativePG performs an offline in-place major upgrade when you declare an image with a higher major version: it shuts the cluster down, runs pg_upgrade with --link in a dedicated job, and recreates the replicas afterwards. When downtime is not acceptable, the same documentation covers the online route through logical replication into a new cluster.
One caveat belongs in every runbook. After a major upgrade, pre-upgrade backups cannot be used to recover to a point after the upgrade, so the first task afterwards is a fresh base backup. With the Barman Cloud plugin it is also worth changing serverName at the same time as the image, so WAL from the two major versions lands in separate archive paths.
Pooling and rolling changes
Connection pooling is declared with a Pooler resource, which runs PgBouncer in front of the -rw or -ro Service and follows it through a failover. Roles, databases, extensions and schemas can be managed declaratively on the Cluster, so the thing a developer reads in the repository is the thing that exists in the database.
The drain behaviour from the opening comes from the same place. Every Cluster ships with two PodDisruptionBudgets; a drain that would evict the primary triggers a switchover first, and in clusters of three or more instances only one replica at a time is shut down. None of that choreography lives in a runbook, because the operator performs it.
Why a generic provisioner cannot match this
It reconciles a resource, not a system
A generic provisioning layer, whether it is Terraform, a universal control plane composition, or a chart that renders a StatefulSet, works by comparing a declared resource with what exists and closing the gap. That model is excellent for things whose correct state can be written down in advance: a bucket, a DNS zone, a network.
Which instance is the primary is not one of those things. It is an observed fact that changes because of a failure, and the correct response depends on data only Postgres can report. A desired-state reconciler has nowhere to put "promote whichever replica has received the most WAL", because that is not a field in a spec. It is a decision taken at runtime.
A generic layer sees a Pod that failed a probe and restarts it. The operator sees a Postgres cluster that lost its primary and elects a new one.
Failover and PITR need database-aware logic
Look at what a correct failover actually requires: reading the replication position of every replica, promoting one of them, repointing the write endpoint, fencing the old primary so it cannot keep accepting writes, and later rewinding it so it can rejoin as a replica. Point-in-time recovery needs a base backup, an unbroken WAL archive, and a restore process that stops replay at a target. A generic provisioner has no mechanism for any of it, because none of it is expressible as "make this object look like that one".
Capability | Generic provisioning layer | CloudNativePG |
|---|---|---|
Create instance, database, role | Yes | Yes, declaratively on the Cluster |
Automated failover | No concept of primary or replica | Promotes the most advanced replica, moves -rw |
Fencing an isolated primary | No | Isolated primary shuts down within the probe timeout |
Continuous WAL archiving | No | Barman Cloud plugin, to S3, GCS or Azure |
Point-in-time recovery | Restore a snapshot, if one exists | Base backup plus WAL replay to a timestamp |
Minor upgrade | Recreate pods with a new image | Replicas first, then switchover of the primary |
Major upgrade | Hand-written runbook | Declarative pg_upgrade, or logical import |
Node drain | Pod is evicted, writes fail | Switchover before eviction, via PodDisruptionBudgets |
You would rebuild CNPG, badly
Teams that start with a generic layer do not stop at provisioning. The first incident adds a failover script. The first restore request adds a WAL archiving sidecar and a runbook. The first major upgrade adds a job and a checklist. Two years later there is a Postgres operator inside the platform, undocumented, tested only by the incidents that produced it, and maintained by whoever wrote the last script.
That is the outcome we design against. If the lifecycle has to be encoded somewhere, it should be encoded in a component whose whole purpose is that lifecycle, with its own release process, test suite and community watching the failure paths.
Why CNPG and not the other Postgres operators
Once the choice is a Postgres-specific operator, CloudNativePG is not the only candidate, and the comparison is worth making against named tools rather than a category.
Zalando: Patroni and Spilo
The Zalando Postgres Operator is one of the oldest in the space and runs a lot of production databases. It deploys Spilo, Zalando's image that bundles Postgres with Patroni for high availability and WAL-G for backups, and the operator manages clusters of those pods.
It is battle-tested, and the trade is that you inherit the whole stack. High availability lives in Patroni inside the image, backups live in Spilo's configuration, and operating it well means understanding three projects and how Zalando composed them. For a team already fluent in Patroni that is an asset. For a team that wants the Kubernetes API to be the single place where cluster state lives, it is an extra layer.
Citus: scale-out, a different problem
Citus is often mentioned in the same breath, but it answers a different question. It is a Postgres extension that shards tables across a coordinator and worker nodes, for workloads that have outgrown a single primary. There is no first-party Citus operator; on Kubernetes it usually arrives through Patroni's Citus support or through StackGres sharded clusters.
Distributing data does not remove the lifecycle work. Every shard is still a Postgres instance that needs failover, backups and upgrades, and you now have many of them plus a coordinator. If a workload needs horizontal write scaling, Citus is a real answer. For the typical service database that fits comfortably on one primary with replicas, it solves a problem that does not exist yet and multiplies the one that does.
Crunchy PGO, Percona and StackGres
Crunchy PGO pairs Patroni with pgBackRest, which is a strong backup tool with parallel and incremental restore. The Percona Operator started from PGO and is now a hard fork with the same Patroni and pgBackRest design. StackGres bundles Patroni, PgBouncer, backups, monitoring and a web console into one opinionated package.
Operator | High availability | Backups | What you take on |
|---|---|---|---|
CloudNativePG | Instance manager, Kubernetes API | Barman Cloud plugin, volume snapshots | One operator plus its backup plugin |
Zalando | Patroni inside Spilo | WAL-G in Spilo | The Spilo image and its conventions |
Crunchy PGO | Patroni | pgBackRest | Two external projects composed by the operator |
Percona | Patroni | pgBackRest | As PGO, on an independent fork |
StackGres | Patroni | Built-in, plus sidecars | A full bundle with its own console |
Citus | Depends on how it is deployed | Per node | A sharded topology, many instances to operate |
All of these are credible. We lead with CloudNativePG for a specific reason: it keeps the moving parts to the operator and Postgres itself, with no second consensus system beside the Kubernetes API. When something goes wrong at night, there is one controller to read, one set of events, and one project's documentation that explains the failure path.
The KISS principle in practice
One operator, one job
CloudNativePG installs on its own, manages one kind of workload, and does not ask the rest of the platform to be shaped around it. That matches how we build everything else. We describe cloud infrastructure with a versioned Terraform module library rather than a universal control plane, we run external-dns for DNS, and when the DigitalOcean webhook for it needed an owner, we took that on rather than reinventing it.
Depth beats breadth for state
Stateless workloads forgive shallow tooling, because the worst case is a restart. Stateful ones do not. The difference between an operator that knows what a timeline is and a layer that knows what a Pod is only appears during failures, which is exactly when you cannot afford to discover it.
Less to build, test and carry
Every custom abstraction is code the team owns forever: tested by its authors, understood by the people who remember why it exists. A specialised operator moves that burden to a project with a release cadence, a test suite that exercises failover paths, and users who report bugs before you hit them. The same cluster definition also becomes cheap to reuse: in our preview environments, each pull request gets its own CloudNativePG instance restored from a QA snapshot, created and deleted in the same cascade as the rest of the Application.
The trade-offs we accept
Another operator to run
CloudNativePG ships a minor release roughly every three months, and each minor version is supported until three months after the next one. Staying on a supported version is a recurring task, and deprecations are real: the in-tree Barman Cloud integration has been deprecated since 1.26 and is scheduled for removal in 1.31.
Operators are also software with vulnerabilities. In May 2026 the project published CVE-2026-44477, a critical issue in the metrics exporter, together with fixes for three bugs in the failover path. The fix was a patch release, and taking it quickly is the price of running the component rather than renting it. We plan for that cadence instead of discovering it.
Postgres only, on purpose
CloudNativePG does nothing for MySQL, Redis or anything else. A different datastore means a different specialised tool, and we see that as the design working. A single abstraction that promises every database tends to deliver the lowest common denominator of each, and the lowest common denominator of database operations is provisioning.
When a managed database wins
For some teams the right answer is not to run Postgres in the cluster at all. If there is no one who will own database operations, if compliance requires a provider's certified service, or if the database is the one component that must outlive every cluster rebuild, a managed service such as Amazon RDS or Cloud SQL buys that operational depth from someone else. The criterion does not change: pick the option that covers the lifecycle. A managed database covers it by contract; CloudNativePG covers it in the cluster, next to the application, declared in the same repository and migrated through the same sync.
Match the tool to the workload
Provisioning is where comparisons start because it is the part that is easy to demonstrate. It is also the part that tells you nothing. The question worth asking of any Postgres setup on Kubernetes is what happens on the worst night of the year: the primary's node is gone, someone ran the wrong statement an hour ago, and the next major version is due. A generic layer answers with a runbook. A Postgres-specific operator answers with a controller that has already done it.
That is why we choose by scope. The scope here is the database lifecycle, and CloudNativePG is the smallest component that covers all of it.
When did you last restore to a timestamp?
Not a backup job that reports success. A real restore, to a specific second, into a new cluster, timed end to end. If the honest answer is "never" or "we would have to check the runbook", that is the gap worth closing before the night it matters. We map what your Postgres setup does on failover, restore and upgrade, and what it would take to make each of them boring.
A technical conversation about your setup, not a sales call
SHARE ON SOCIAL MEDIA