
Someone opens the Jobs list in a namespace that has been live for a month and finds forty-one completed migration Jobs where they expected three. The first reaction is that something is misconfigured, and the second is to go looking for the setting that makes the hook run only when the schema changed. There is no such setting. Nothing is misconfigured. Those forty-one Jobs are the system working as designed, and thirty-eight of them did nothing at all and took about two seconds each.
There is a warning that circulates about running database migrations as Helm hooks under Argo CD. It goes like this: a PreSync hook fires on every sync rather than only on first deploy, so sooner or later it will re-run a migration and corrupt your database. It sounds plausible, it gets repeated in anti-pattern lists, and it makes people design around a problem they do not have.
It is half right. The hook does fire on every sync, and that part is mechanically true and worth understanding properly. The conclusion does not follow, because whether a re-run is harmful depends entirely on whether the migration remembers what it already did.
Our position is that a hook running on every sync is safe by design. What actually breaks is migration design: migrations with no history of their own, migrations slow enough to block a deployment, and migrations that destroy something a rollback still needs.
This article walks through the mechanics of the every-sync behaviour, the two-phase split that keeps it fast, what a migration Job should actually contain, and the one rule that makes rollback a non-event.
The warning, and the half of it that is wrong
"PreSync hooks fire on every sync" is true
Concede the accurate part first, because it is the part people get right. Annotate a migration Job as a Helm pre-install or pre-upgrade hook, deploy it through Argo CD, and that Job runs every single time the Application syncs. Not once. Not on version changes only. Every sync, including the one that changed a log level.
"And will break your database" does not follow
The leap from "it runs every time" to "it will corrupt your data" assumes the migration has no memory. That assumption holds for exactly one kind of migration: hand-written DDL in a Job that executes whatever statements it contains, unconditionally, every time it starts.
Any migration tool worth using does not work that way. It maintains its own record of which migrations have already been applied, in a table inside the database it is migrating. On start it takes a lock, reads that record, compares it to the migrations shipped in the image, and applies only what is missing. Run it against an up-to-date database and it finds nothing to do, exits zero, and the whole thing takes a couple of seconds.
We do not standardise on one tool across clients. We use whatever migration tooling the project's framework already provides, and that is genuinely fine, because the choice of tool is not where the risk lives. The one hard requirement is that the tool records which migrations have already been applied. Once it does, running it again causes no problems and the entire every-sync objection disappears.
One clarification that matters when you audit this: idempotency here is a property of the runner, not of each individual migration. A single migration does not have to be written so that ADD COLUMN can run twice. It has to be recorded as applied so that it never runs twice. That distinction decides where you look when something does go wrong.
How Argo CD actually handles Helm hooks
Both annotations map to the same phase
Argo CD renders the chart itself rather than letting Helm manage a release, and it translates Helm hook annotations into its own hook phases. The mapping is not one to one. Here is the annotation block we actually use on a schema migration Job.
Both hook events are present, and both collapse into the same Argo CD phase: PreSync. There is no path through which one applies and the other does not.
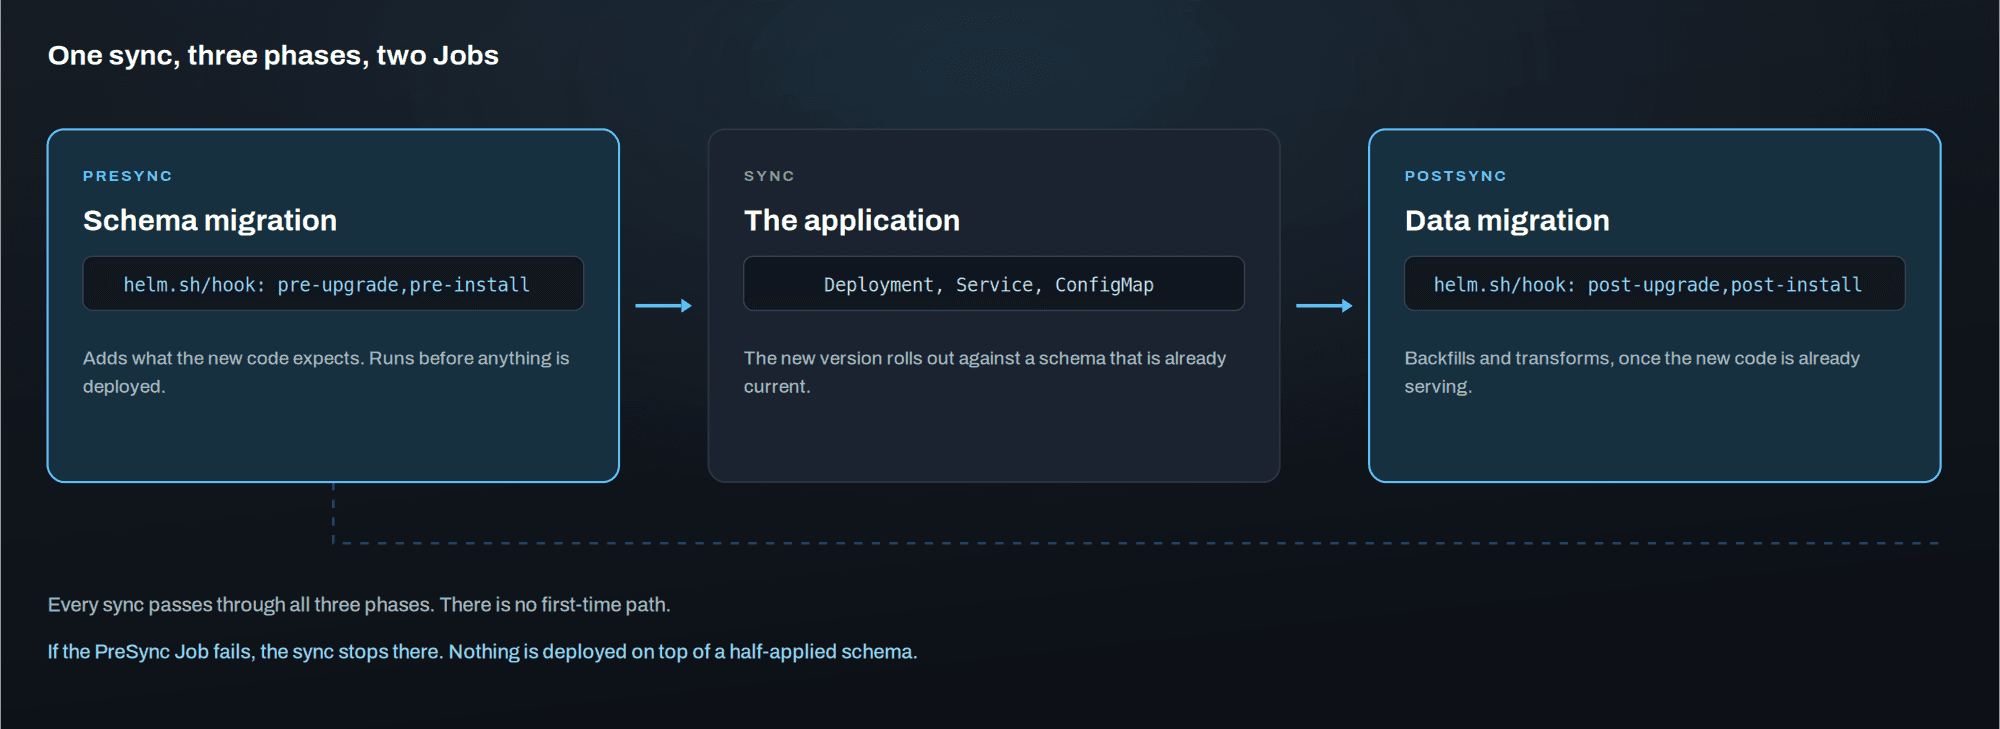
Every sync passes through all three phases. The schema Job runs before anything is deployed, and the data Job runs once the new version is already serving.
There is no install versus upgrade, only a sync
The reason is simple once stated. Helm distinguishes a first install from a subsequent upgrade because Helm tracks releases and knows which operation it is performing. Argo CD does not have that concept. It has a sync: render the desired state, compare it to live state, apply the difference. It changes only what the manifests actually changed, but a hook is not part of the diff. A hook is a phase, and every sync passes through every phase.
This is not an oversight. Reconciliation is a convergence loop, and a convergence loop has no notion of "first time". Asking it to run something once would mean asking it to carry release history it deliberately does not keep.
One consequence is worth pulling out, because it is the safety property people miss while worrying about the re-runs. Phases are ordered and gated. If the PreSync Job fails, the Sync phase never starts. The new version is not deployed on top of a schema that is half migrated; the Application stops, unhealthy and unmistakable, with the failed Job and its logs still in the namespace. Compare that to running migrations from a pipeline step next to the deploy, where the ordering guarantee is whatever the pipeline author remembered to write.
What hook-weight and hook-delete-policy actually control
The two companion annotations do specific jobs, and both matter in practice.
hook-weight: "-1" orders this hook ahead of others in the same phase. Argo CD maps Helm's hook weight onto its own sync waves, and both run in ascending order, so a negative weight puts the migration first, before anything else that might depend on the schema being current.
hook-delete-policy: before-hook-creation deletes the previous hook Job before creating the next one. Without it you accumulate completed Jobs, and a Job with the same name as an existing one fails to create at all. This is what makes the every-sync behaviour operationally clean rather than a source of clutter and name collisions.
Two details about deletion policies are worth knowing before you need them. BeforeHookCreation is what Argo CD assumes when no policy is set, and it is the right choice for migrations specifically because it keeps the last Job in the cluster: when a migration fails at two in the morning, the Job and its logs are still there to read. HookSucceeded deletes the Job as soon as it passes, which is fine for a smoke test and unhelpful for a migration.
The other detail is a trap. Kubernetes Jobs support ttlSecondsAfterFinished, and setting it on a hook Job makes the resource disappear on its own schedule, which Argo CD reports as OutOfSync because live state no longer matches the rendered manifest. Let the delete policy handle cleanup and leave the TTL alone.
Helm hook | Argo CD phase | When it runs |
|---|---|---|
pre-install | PreSync | Every sync. Argo CD does not distinguish install from upgrade. |
pre-upgrade | PreSync | Every sync. Same phase as pre-install. |
post-install | PostSync | Every sync, after the resources report healthy. |
post-upgrade | PostSync | Every sync. Same phase as post-install. |
post-delete | PostDelete | When the Application's resources are deleted. |
pre-rollback, post-rollback | Not supported | Ignored. Argo CD has no rollback phase to hook into. |
test | Not supported | Ignored. |
The last two rows are the ones that surprise teams migrating from plain Helm. If your chart relied on a rollback hook to undo something, that mechanism does not exist here, and the section on add-only migrations below is the reason we do not need it.
What the migration Job actually contains
Most articles show the annotations and stop. The Job body is where several practical decisions live, so here is the whole thing.
Four things in there are deliberate.
The image is the application image at the tag being deployed, not a separate migration image. The migrations that run are exactly the ones the incoming version ships, which is the whole point of running them in PreSync: the schema is brought to the state the new code expects, using the new code's own definition of that state.
backoffLimit and activeDeadlineSeconds bound the failure. Without a deadline, a migration blocked on a lock will sit there until someone notices, holding the sync open. With one, the Job fails, the sync fails, and you get told.
lock_timeout is the setting that turns a lock queue into a fast, clear failure on PostgreSQL. A DDL statement that cannot get its lock waits, and while it waits it blocks every query behind it on that table, which is how a small ALTER becomes an outage. A five-second lock timeout means the migration gives up instead, and you retry it deliberately rather than discovering it during a traffic peak.
restartPolicy: Never with a small backoffLimit keeps retries visible as separate pod attempts rather than an invisible restart loop inside one pod.
One thing the Job does not need is concurrency control of its own. Two syncs cannot usefully run migrations at once, and every serious migration tool takes a lock in the target database before it reads its history, so the second runner waits rather than racing. It is worth confirming that your tool does this rather than assuming it, because the ones that do not are exactly the ones that will hurt you on a retry.
Two kinds of migration, two phases
Here is the practice most treatments of this topic leave out, and it is the one that answers the objection people actually care about. There is not one migration. There are two, and they belong in different phases because they have opposite requirements.
Schema migration | Data migration | |
|---|---|---|
Phase | PreSync | PostSync |
Annotation | pre-upgrade, pre-install | post-upgrade, post-install |
Runs | Before the new code is deployed | After the new code is live and serving |
Contains | New columns, tables, indexes | Backfills, transforms, row rewrites |
Expected duration | Seconds | Minutes to hours |
Blocks the deployment | Yes, by design | No, the deployment already finished |
Schema first, because the new code needs room
The schema migration's job is narrow: add what the new version expects, so that when it starts, the schema it was written against is already there. Because all it does is make room, it is fast. Adding a nullable column is a catalogue change on PostgreSQL, and since version 11 adding a column with a constant default no longer rewrites the table either. It finishes in about the time it takes to connect.
Data after, because the heavy work should not sit on the critical path
Backfills, transforms and anything that touches a large number of rows go in the PostSync Job, which runs once the new code is already serving traffic. The annotation block is the same shape.
The strongest objection to hook-based migrations is not really about idempotency. It is about time: will a big migration block every sync, including the emergency one at two in the morning that has nothing to do with the schema? The split is most of the answer. A schema change that only adds is quick, so the pre-deploy hook stays short. The slow work is data work, and data work runs afterwards, where its duration costs the deployment nothing because the deployment already finished. A twenty-minute backfill takes twenty minutes either way. The difference is whether those twenty minutes sit on the critical path or behind it.
This has a design consequence worth naming rather than discovering. Because the data migration runs after the new code is already serving, that code has to tolerate the intermediate state where the schema is current but the data is not fully transformed. It reads the new column when it is populated and falls back when it is not. That is a real constraint, and it is the same constraint any zero-downtime deployment imposes. Accept it deliberately.
Why running on every sync is safe
The tool records what it applied
The mechanism is unglamorous. The tool keeps a history table in the target database listing the migrations it has run there. On each start it reads that table, works out which migrations in the image are not represented, and applies those. Applying nothing is a normal, expected outcome, not an error.
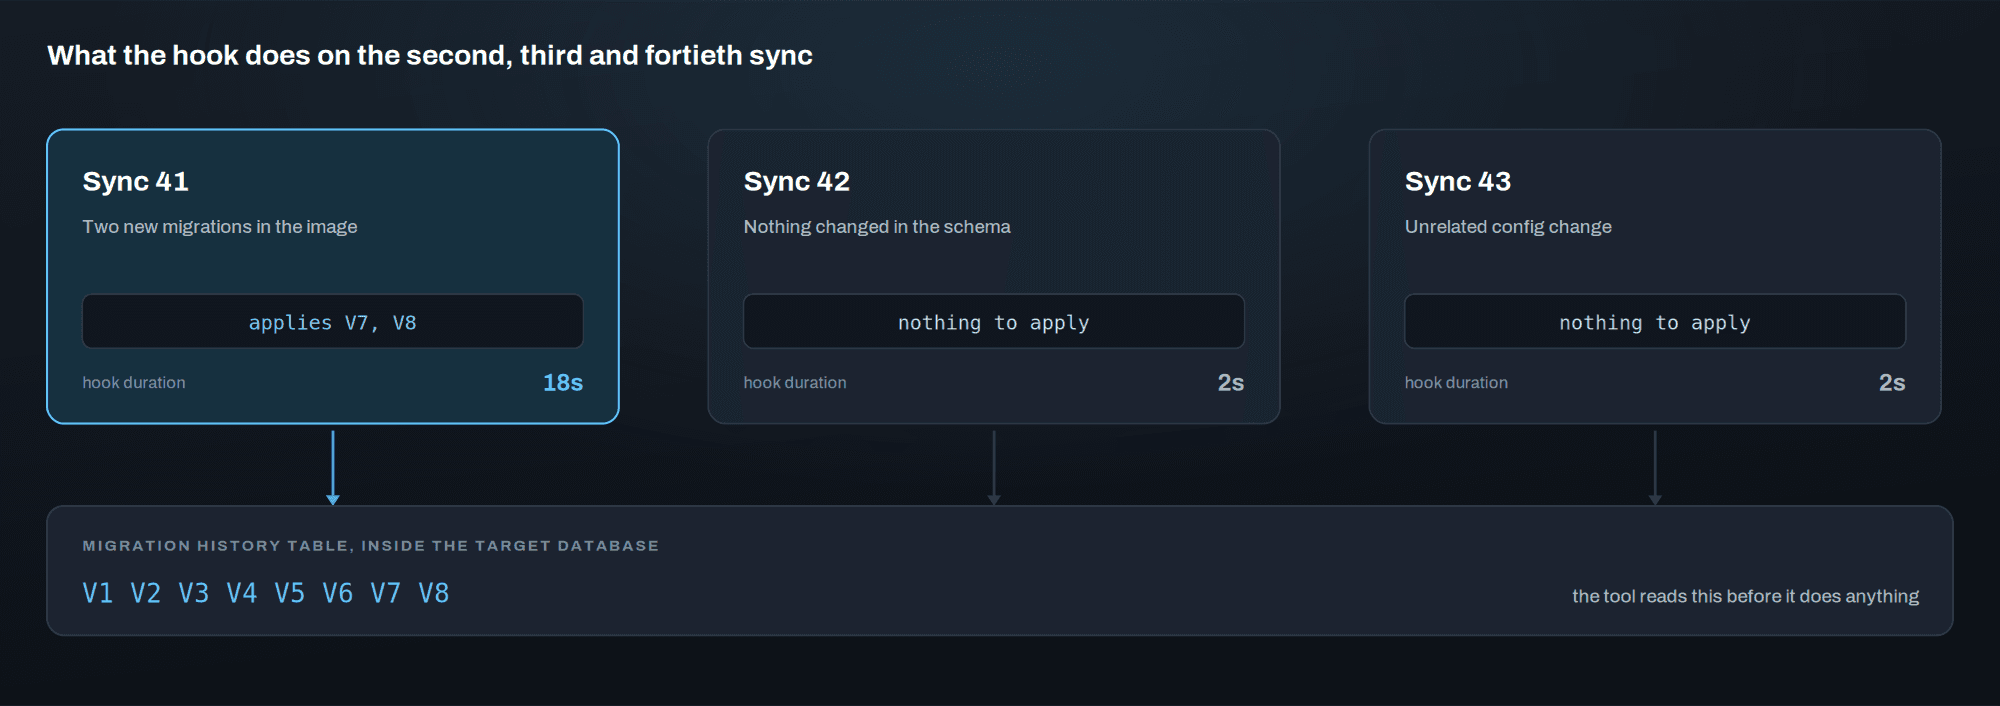
The history table lives in the database being migrated, so each environment knows exactly how far it has got. A re-run reads it and exits.
A no-op costs seconds and buys ordering
Those few seconds are not wasted. They buy a guarantee that is difficult to get any other way: the migration has definitely run before the new code starts. Not probably, not usually. The phase ordering enforces it on every deployment, without anyone remembering to check.
Compare that to the alternative people reach for, which is running migrations conditionally from a pipeline step when someone judges that the schema changed. That judgement is a human input, and human inputs are where deployment procedures go wrong. Paying two seconds per sync to remove a judgement call from the path is a good trade.
Infrastructure does not know what changed in the code
This is the answer we give when someone asks why the hook is not smarter about when it fires. The delivery layer has no knowledge of what changed inside the application or what the new code requires. It cannot inspect a code diff and conclude that this release needs a schema change and the previous one did not. That information is not available to it, and building a mechanism to make it available would mean coupling the deployment layer to the application's internals.
So it runs the migration every time, by default, and the tool's own history is what makes that unconditional re-run cheap rather than reckless. The tool decides whether there is work to do, because the tool is the only party that actually knows.
Where hook-based migrations genuinely break
Three failure modes are real. None of them is caused by the hook, and that distinction matters because it tells you where to fix them.
Non-idempotent raw DDL
A Job that executes a fixed list of statements with no record of what it already ran will fail on the second sync, and it will fail in an ugly way: column already exists, or worse, a data transformation applied twice. This is a property of how the migration was written, not of when the hook fires. Move the same DDL into a tool that tracks its history and the identical hook configuration becomes safe.
The useful way to think about it: the hook is a scheduler. It runs what you gave it, at a defined point, as many times as the phase occurs. Everything about whether that is safe lives in what you gave it.
One related hazard belongs here, because it produces the same symptom for a different reason. On PostgreSQL, DDL is transactional, so a migration that fails halfway rolls back cleanly and the retry starts from a known state. On MySQL, most DDL commits implicitly, so a migration containing three statements that fails on the third leaves the first two applied and unrecorded. The retry then hits "column already exists" and the history table says the migration never ran. The fix is a convention rather than a tool: one schema change per migration file, so a partial failure is not possible.
A migration that is slow because of locks, not size
A hook that takes twenty minutes blocks the sync for twenty minutes, every sync, whether or not the deployment has anything to do with the schema. The schema and data split above removes most of that by construction. What remains is the case where a statement that looks trivial takes an aggressive lock, and on a busy table the lock is the outage, not the duration.
What you wrote | What it does under load | What to write instead |
|---|---|---|
CREATE INDEX | Takes a SHARE lock and blocks writes for the whole build | CREATE INDEX CONCURRENTLY, in its own migration with the wrapping transaction disabled |
SET NOT NULL | Full table scan under an ACCESS EXCLUSIVE lock | ADD CONSTRAINT ... CHECK (col IS NOT NULL) NOT VALID, then VALIDATE CONSTRAINT separately |
ADD COLUMN with a volatile default | Rewrites the whole table | Add the column nullable, set the default, backfill in batches in the PostSync Job |
Changing a column type | Rewrites the whole table | New column, dual write, backfill, switch reads, drop later through a release |
The first row has a detail that catches people out. Every tool has a way to opt out for a single migration, and the practical rule is that a concurrent index gets a migration file to itself. It is also the one operation where a failure leaves an invalid index behind that has to be dropped before the retry.
The genuinely unavoidable case is a schema change on a very large table on an engine that rewrites rather than updating metadata. That one is handled on its own terms, usually by performing the change out of band and letting the migration recognise it as already applied.
Code and schema roll back separately
Argo CD can roll an Application back to a previous revision. That rolls back manifests. It does not roll back the schema, because the schema is not in the manifests and never was. So in the general case a rollback puts the old code in front of a newer schema, and whether that works is entirely a property of how the migration was written. This is the failure mode with the most severe consequences and the simplest fix, which is the subject of the next section.
The pattern that holds up: add-only
Migrations only add; deletes go through a release
The rule we follow is that forward migrations only create or add. A migration may introduce a column, a table, an index, or a constraint that permits what already exists. It does not drop, rename, or narrow anything.
Destructive changes are not forbidden, they are deliberate. Dropping a column happens through its own release, scheduled once nothing depends on the old shape any more, with the knowledge that this release is the point of no return. Separating the two makes the destructive step a decision someone makes on purpose rather than a side effect of shipping a feature.
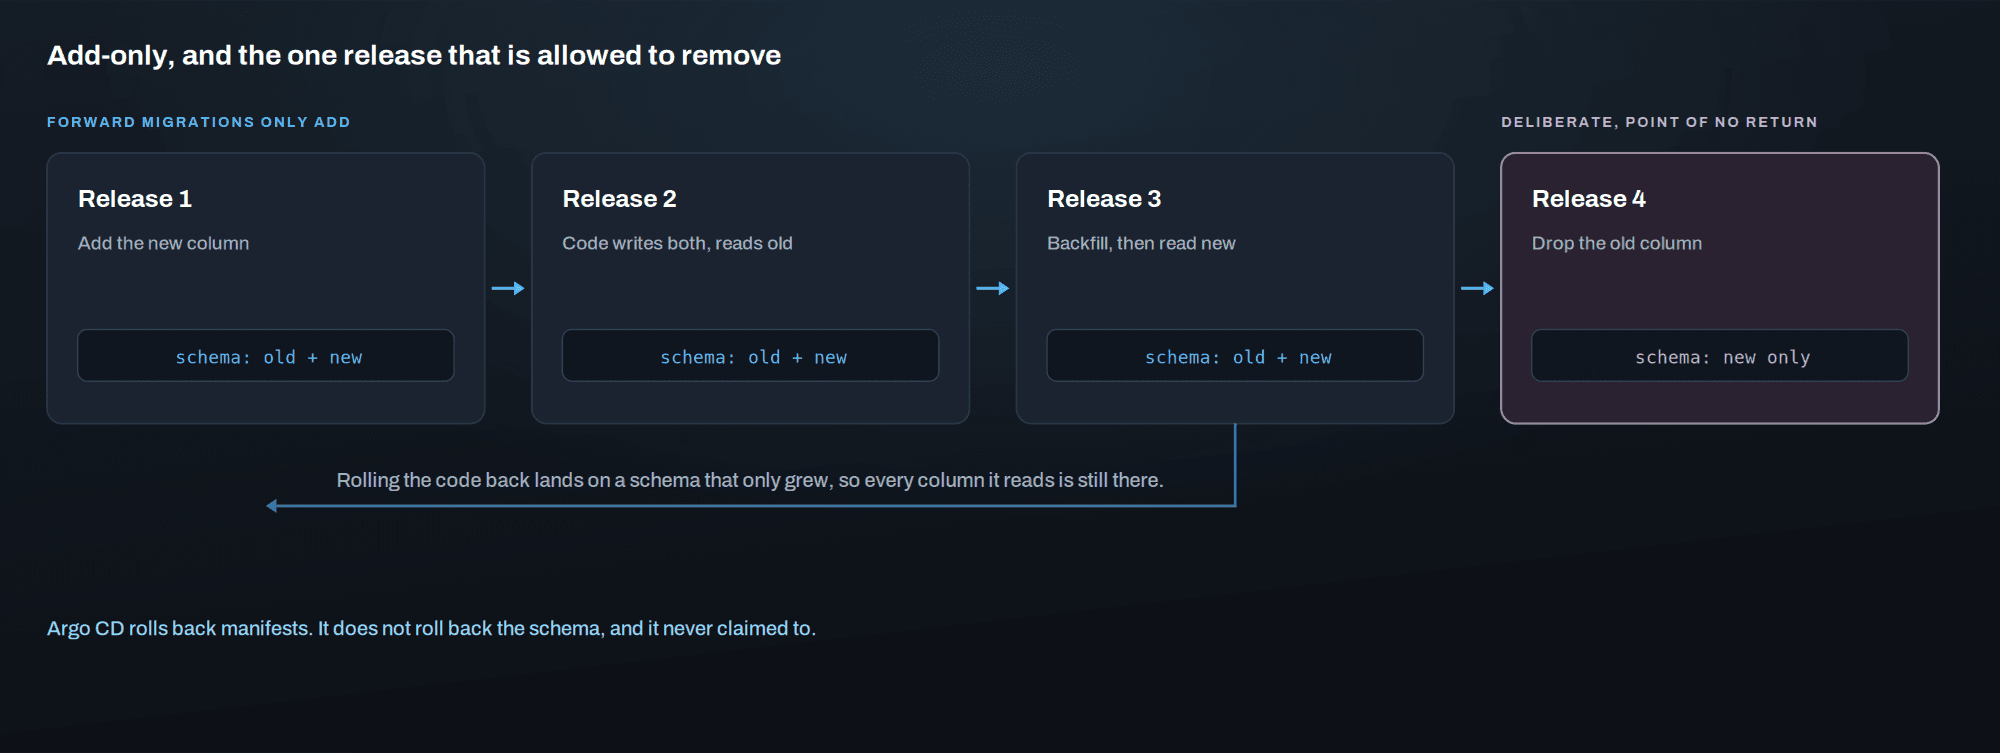
Because the schema only ever grows, rolling the code back never lands on a schema that removed something the older version still reads.
A rename is the clearest example, because the naive version is one migration and the safe version is four releases. Add the new column. Ship code that writes both and reads the old one. Backfill in PostSync, then ship code that reads the new one. Only after that, in a release of its own, drop the old column. Every step up to the last is reversible by rolling the code back, because the schema at each point still contains everything every recent version reads.
Why this makes rollback safe
The consequence is direct. If every forward migration only added, the schema at any point in time is a superset of the schema at every earlier point. Roll the code back one version and it still finds every column it reads, because nothing was taken away. This is the practical form of the expand and contract pattern, stated as a rule a team can hold to rather than a technique to remember under pressure. Expand in the migration. Contract only through a separate, intentional release.
The tool is the source of truth for what ran
The same mechanism answers a question people usually treat as separate: how do you stop staging and production drifting apart? The migration tool records in each environment's own database which migrations have run there. Staging's history lives in staging, production's lives in production, and each environment converges on the same schema by replaying the same ordered set of migrations.
Be precise about the division of responsibility here. Argo CD guarantees that staging and production have the same manifests. It has no view of the schema at all and never claimed to. Parity of schema comes from the migration tool's history, not from the reconciler. Confusing the two is how teams end up believing GitOps gives them schema parity for free.
The checks that matter
Everything above collapses into a short list. If a migration setup passes it, the hook is a solved problem.
The migration tool records what it applied, in the target database, and takes a lock before it reads that record.
Schema migrations run as PreSync, from the application image at the tag being deployed.
Data migrations run as PostSync, and the new code tolerates the state where the schema is current but the data is not backfilled yet.
Hook Jobs carry hook-delete-policy: before-hook-creation, and no ttlSecondsAfterFinished.
Jobs are bounded with backoffLimit and activeDeadlineSeconds, and PostgreSQL Jobs set a lock_timeout.
Forward migrations only add. Drops and renames ship as their own release.
Concurrent index creation lives in its own migration with the wrapping transaction disabled.
The hook is not the risk; the migration design is
Put the pieces together and the every-sync warning stops being frightening. A migration that is recorded, split into schema before the code and data after it, and add-only makes the hook a solved problem. It runs every sync, it usually does nothing, and the few seconds it costs buy an ordering guarantee that removes a human judgement from the deployment path.
If migrations do not have those properties, the hook is not what broke. It is where a design decision that was already wrong becomes visible, which is arguably the most useful thing it could do. A migration that cannot survive being re-run has a problem that will surface eventually, on a retry, a rerun, or a parallel deployment. Better it surfaces on an ordinary Tuesday sync than during a recovery.
If your migrations do not pass that check yet
Getting from where a team is now to recorded, phase-split, add-only migrations is usually a smaller job than it looks, and most of it is convention rather than tooling. We map what runs where, what is safe to re-run, and what has to move off the critical path.
Talk to an engineer. A technical conversation about your setup, not a sales call.
SHARE ON SOCIAL MEDIA